

Published on
MLOps for SMBs: Start With a Pilot, Not a Platform
Yes, small and medium businesses can implement MLOps effectively, and the path runs through a scoped pilot rather than a full platform build. We have seen the pattern hold across industries: pick a narrow use case, lean on managed cloud tools or lightweight open source, bring in fractional expertise where the gaps show up, and measure results before expanding. The first move is simple: run an AI readiness check and define one pilot small enough to finish in weeks.
TL;DR:
Set a 6 to 8 week pilot around one measurable use case, with a defined dataset, user group, and success threshold chosen before building.
Start with existing transaction, support, or inspection records; transfer learning can help smaller datasets, so a pilot need not wait for millions of labeled examples.
Use managed cloud tools for speed; consider lightweight open source after validating demand, if an engineer can run infrastructure and long term cost control matters.
Name an internal process owner, use fractional engineers for the build, and train one or two staff members to monitor outputs and flag anomalies.
Track drift, accuracy, latency, and errors from launch, with threshold alerts, human review for consequential decisions, and a rollback to the last reliable version.
BRDGITStart Your MLOps Pilot With ReadinessBRDGIT helps businesses assess AI readiness, identify practical opportunities, and build a roadmap for turning a focused pilot into execution.Explore AI readiness support
Table of Contents
Why MLOps Matters for Smaller Teams and How to Gauge Readiness
Common MLOps Challenges SMBs Face and How to Work Around Them
Architecture Patterns That Fit an SMB Budget
Cost Optimization and Realistic Budget Guidance
Monitoring, Maintenance, and Keeping Models Reliable
Build, Buy, or Hire Fractional Support: Choosing the Right Path
A Practical Roadmap From Pilot to Production
How BRDGIT Supports SMBs Through Practical MLOps Adoption
Connecting MLOps Pipelines With the Systems You Already Run
Why Pilots and Fractional Talent Win for Smaller Teams
Start With an AI Readiness Assessment
FAQ
Sources
Why MLOps Matters for Smaller Teams and How to Gauge Readiness
Operational machine learning earns its keep when it removes a bottleneck someone already feels: a manufacturer cutting inspection time with a defect-detection model, a distributor forecasting demand instead of guessing at reorder points, a staffing firm matching candidates faster than a human recruiter can sort resumes. The return shows up in hours saved, errors avoided, or revenue protected, not in the sophistication of the model itself.
The mistake most SMBs make is skipping straight to tooling before asking where they actually stand. A compact maturity model works better than an enterprise framework built for teams ten times their size:
Draft stage: ideas exist, no model is in production, data lives in scattered spreadsheets or siloed systems.
Pilot stage: one model runs against real data for a defined group of users, with a human checking its output.
Operational stage: the model runs continuously, feeds a real workflow, and has basic monitoring attached.
Automated stage: multiple models run with minimal manual oversight, retraining is scheduled, and governance is documented.
Kellogg’s research on AI adoption stages found that most organizations sit at the earliest level of automation and benefit from locating themselves honestly on that scale before setting goals. A business that mistakes “draft” for “operational” tends to overbuild infrastructure it does not yet need, while one that underestimates its own readiness stalls on tooling debates instead of shipping a pilot.
Whichever stage applies, success criteria should be concrete from day one: time saved per task, percentage reduction in manual error, or a direct revenue or cost figure tied to the use case. Vague goals like “explore AI” rarely survive a budget review; a pilot that promises to cut order-entry errors by a measurable amount gets funded again.
Common MLOps Challenges SMBs Face and How to Work Around Them
The obstacles are predictable: thin data, thin staffing, systems that were never built to talk to each other, and a budget that cannot absorb a failed six-month project. None of these rule out MLOps. They just change the shape of the solution.
Data readiness is usually the first worry, and it is often overstated. Most SMBs already sit on years of transactional logs, support tickets, or inspection records that went unused simply because nobody structured them for modeling. Academic work on small-sample methods shows that Bayesian transfer learning can produce strong predictive performance even on small datasets, which matters directly for a business that cannot collect millions of labeled examples before starting. Reusing existing logs and applying transfer learning from a pretrained model narrows the data problem considerably.
People and skills are the next blocker. Few SMBs can justify a full MLOps team, and few need one. A pragmatic path looks like this:
Assign a lean product owner internally who understands the business process, even without deep ML background.
Bring in fractional engineers for the technical build so the business avoids a full-time hire for a part-time need.
Cross-train one or two staff members to monitor outputs and flag anomalies once the pilot runs.
Document decisions as you go so the next phase does not depend on one person’s memory.
Integration and deployment worries are usually solved with less engineering than teams expect. A containerized endpoint behind a simple API, or a managed inference service from a cloud provider, removes most of the infrastructure burden. CSET’s guidance on AI standards for small and medium enterprises points directly at this approach, recommending that SMEs lean on cloud AI-as-a-service to reduce operational burden while limiting scope through pilots rather than building custom infrastructure from scratch.
Cost control deserves its own discipline from the start: schedule training jobs during off-peak hours, use spot instances where interruption tolerance allows, set billing alerts before the first invoice arrives, and curate datasets rather than hoarding raw data that adds storage cost without adding signal.
Governance does not need a committee. It needs scope limits on what the model is allowed to decide, a human reviewing outputs during the pilot phase, and a staged rollout that expands only after the model proves itself on a small slice of real traffic.
Pro Tip: Start your pilot with a model that assists a human decision rather than replacing it outright; it builds trust faster and limits the damage of an early mistake.
Architecture Patterns That Fit an SMB Budget
The right architecture depends less on ambition and more on constraint. Three patterns cover most SMB situations.
The managed cloud pattern (Vertex AI, SageMaker, and similar platforms) trades some control for speed. A small team gets model registry, deployment, and basic monitoring out of the box, at the cost of a steeper price curve as usage scales and less flexibility to customize deep internals. Tool comparisons aimed at small business MLOps needs consistently list these managed platforms alongside lighter open-source options, which tells us both paths are common, not that one universally wins.
The lightweight open-source pattern (MLflow for tracking and registry, BentoML-style serving for deployment) suits a team with at least one engineer comfortable running infrastructure, and it avoids vendor lock-in and recurring platform fees. It tends to make sense once a business has validated a use case through a managed pilot and wants to control long-term cost as volume grows.
A hybrid pattern applies when a specific constraint forces the issue, most often data residency rules that require models to run on-premises or in a specific region, or latency requirements that managed cloud endpoints cannot meet. In these cases, teams often run inference locally while using managed tools for training and experiment tracking.
Whichever pattern you choose, four components come first:
A single source of truth for data, even if it is a well-organized data warehouse rather than a full lakehouse.
A model registry that tracks which version is live and what it was trained on.
A basic CI/CD pipeline that tests and deploys model updates without manual file copying.
Monitoring from day one, even if it starts as a scheduled script rather than a dashboard.
Skipping the registry or the monitoring component to save time early almost always costs more later, when nobody can explain which model version produced a bad prediction six weeks ago.
Cost Optimization and Realistic Budget Guidance
Three cost categories drive most MLOps spend: compute for training, compute for inference, and storage for data and model artifacts, with engineering time (internal or fractional) often outweighing the cloud bill itself in the early stages.
Tactical controls keep the first two in check without heavy process:
Schedule training jobs for off-peak windows where cloud pricing is lower.
Use spot or preemptible instances for non-urgent training runs that can tolerate interruption.
Tag every resource by project and environment so costs are traceable to a specific pilot.
Set billing alerts before the first invoice, not after a surprise one.
Tecton’s documentation on managing infrastructure costs recommends exactly this combination: billing alerts, resource tagging, and scheduled jobs as the practical levers teams reach for first, and these apply just as well to a five-person startup as to a larger engineering org.
A pilot-stage MLOps engagement typically carries a lower, bounded cost than an operational deployment, because modest-budget AI adoption for smaller organizations often relies on off-the-shelf or rules-based tools and free or low-cost assessments before any custom engineering begins. The jump from pilot to operational spend comes from sustained inference volume and the monitoring and retraining infrastructure that a one-off pilot does not need.
A simple total cost of ownership breakdown separates three buckets: one-time setup (data preparation, initial model build, integration), recurring infrastructure (compute, storage, monitoring tools), and recurring human time (oversight, retraining, incident response). Budgeting qualitatively in these bands, pilot versus operational, before committing to a specific dollar figure keeps a small team from either overcommitting early or underfunding the stage where a model actually earns its value.
Monitoring, Maintenance, and Keeping Models Reliable
A model that works on day one will not work forever without attention, and the attention required is smaller than most SMBs assume. Four signals matter most: data drift (the input data shifting away from what the model was trained on), accuracy degradation over time, latency creeping upward, and a rising error rate in production.
A lean monitoring setup does not require a dedicated observability platform. It needs:
A scheduled check comparing recent predictions against actual outcomes on a regular cadence.
A simple dashboard, even a shared spreadsheet or lightweight business intelligence tool, tracking the four core signals over time.
Threshold alerts that flag a team member when a metric crosses a defined line, rather than requiring someone to watch constantly.
MLRun’s documentation on model monitoring architecture describes exactly this kind of setup: credentialed monitoring functions, a controller and writer component, and default drift-detection applications that a small team can adapt without building observability infrastructure from scratch.
Incident response does not need a formal playbook document to be effective. It needs a staged redeploy process (roll back to the last known-good model version within minutes, not hours) and a human-in-the-loop check for any decision the model makes that carries real business consequence. A support ticket routed incorrectly is recoverable; a credit decision made incorrectly is not, and the oversight level should match that difference.
Build, Buy, or Hire Fractional Support: Choosing the Right Path
The decision comes down to five questions: how fast do you need results, how much control do you need over the internals, how sensitive is the data involved, what is the realistic budget, and where does this use case sit on your longer-term roadmap.
Build in-house when the use case is a long-term differentiator for the business and you already have, or plan to hire, the internal capacity to maintain it for years.
Buy a managed service when speed matters more than customization and the use case is close to a solved problem, like document classification or demand forecasting with standard inputs.
Hire fractional support when you need tailored integration with existing systems, want outcomes faster than a from-scratch hire could deliver, and want to avoid the risk and cost of a full-time technical hire before the use case is proven.
Most SMBs land somewhere between the second and third options for a first pilot, shifting toward in-house ownership only after a model has proven its value and the business can justify permanent headcount.
Whichever path you take, the questions to ask a provider or a fractional hire stay consistent: What does the engagement deliver by week six? Who owns the model and the data once the engagement ends? What happens if the pilot does not hit its success metric? A provider who cannot answer these plainly is not ready to run your pilot.
A Practical Roadmap From Pilot to Production
A working rollout sequence looks like this, start to finish:
Run an AI readiness check and pick one use case with a clear, measurable success metric, not three use cases pursued at once.
Scope a 6 to 8 week pilot with a defined dataset, a defined user group, and a specific threshold for what counts as success.
Build an MVP model and choose a deployment path, typically a managed endpoint for speed or a lightweight container when more control is needed.
Monitor results daily during the pilot, set a retraining cadence once it moves toward production, and expand access in stages rather than all at once.
Hand off operations to an internal owner supported by ongoing fractional engineering, rather than letting the pilot quietly lose momentum once the original team moves on.
Pro Tip: Set your pilot’s success threshold before you start building, not after you see the results; a metric chosen in hindsight tends to bend toward whatever the model happened to achieve.
CSET’s guidance on prioritizing protections and pilots for SMEs backs this staged approach directly, recommending that smaller organizations limit scope and prove value before expanding rather than attempting an enterprise-wide rollout from the outset.
How BRDGIT Supports SMBs Through Practical MLOps Adoption
We built our engagement model around the same pilot-first logic, because we have watched too many SMBs stall on infrastructure decisions before proving a single use case works. An engagement typically starts with an AI Readiness Assessment to locate where a business actually stands, followed by an AI Blueprint that scopes a specific pilot with a defined timeline and success metric. From there, the automation build is handled, and fractional engineers step in for the technical implementation and ongoing support to avoid the need for a full-time hire prematurely.
A pilot proves the case before the budget commits to the platform.
A typical structure runs a readiness assessment, a scoped blueprint, a six to eight week build, and a handoff to fractional support for monitoring and iteration, matching the roadmap above rather than introducing a separate process.
Connecting MLOps Pipelines With the Systems You Already Run
Most SMBs are not starting from a blank slate. They have an ERP system tracking orders, a CRM tracking customers, and often a spreadsheet or two holding the data nobody migrated yet. The practical integration question is rarely “how do we build new infrastructure” but “how do we connect a model to what already exists.”
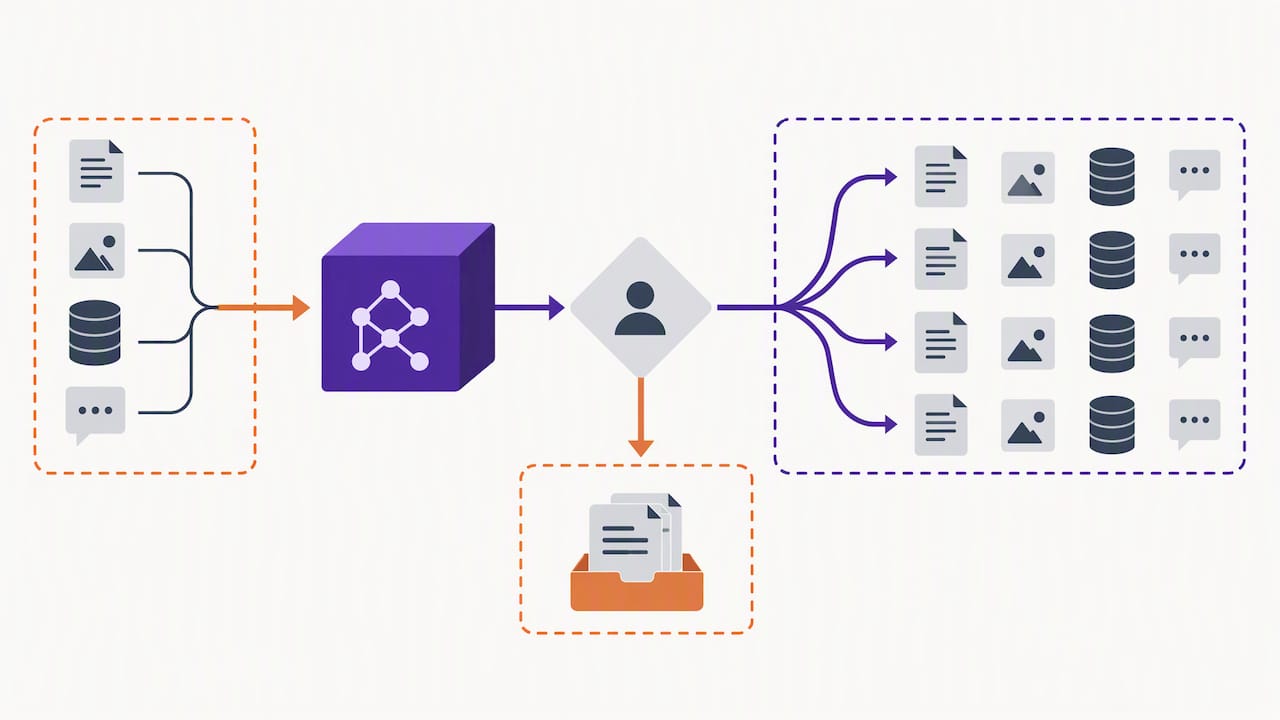
A common pattern pulls data from an existing system through a scheduled export or an API call, feeds it to a model running behind a managed endpoint, and writes the prediction back into the same system a staff member already checks daily, a CRM field, an ERP flag, or a dashboard embedded in an existing tool. This avoids asking employees to learn a new interface for a single use case.
Spreadsheets deserve specific mention, since so many SMB workflows still run through them. When a pilot pulls from spreadsheet data, the privacy and access controls matter as much as the model itself; a useful starting reference is this spreadsheet AI privacy checklist for procurement and security teams evaluating what controls to put in place before connecting a model to that data.
Customer-facing integrations, like a model behind a support chatbot or an automated response system, carry their own governance needs, covered in more depth under monitoring and oversight above, but the integration principle stays the same: connect to the workflow people already use, not the one you wish they used.
Why Pilots and Fractional Talent Win for Smaller Teams
We recommend small pilots because we have watched the alternative play out too many times: a business commits to a year-long platform build, the requirements shift twice before launch, and the team loses faith in AI before it ever sees a result. A pilot that runs six weeks and either works or does not gives a business something a year-long project rarely does, a fast, honest answer.
Fractional talent lowers the stakes further. A business gets the technical expertise a pilot needs without the overhead of a full-time hire it cannot yet justify, and without the risk of that hire sitting idle once the pilot proves out and the real work becomes maintenance rather than invention.
— Team BRDGIT
Start With an AI Readiness Assessment
If any of this sounds like the gap between where your business sits and where it wants to be, the fastest way to close it is not a bigger plan. It is a smaller, well-scoped first step.

We offer a few entry points depending on where you are:
AI Readiness Assessment to find out exactly where your business stands before committing to anything.
AI Blueprint to scope a specific pilot with a clear timeline and success metric.
Fractional Engineer Services to run the build and the ongoing monitoring without a full-time hire.
Check out our AI Readiness Assessment and Blueprint services to scope your first pilot, or explore Fractional Engineer Services if you already know the use case and need the hands to build it.
FAQ
What does MLOps mean for a small or medium business?
MLOps for an SMB means the practices and lightweight tooling that keep a machine learning model reliable once it is in production: tracking which version is live, monitoring its accuracy, and retraining it when performance drifts. It does not require the same scale of infrastructure a large enterprise runs, and CSET’s guidance for smaller organizations recommends scoping it down to pilots rather than full platforms.
How much does MLOps cost for a small company?
Costs vary by use case, but a pilot-stage engagement typically carries a lower, bounded cost than a full operational deployment, since modest-budget approaches for smaller organizations often rely on off-the-shelf tools and free assessments before custom engineering begins. The larger cost usually appears later, once sustained inference volume and ongoing monitoring infrastructure enter the picture.
Should a small business build its own MLOps platform or use a managed service?
Most smaller businesses get faster results from a managed service or fractional engineering support for a first pilot, since building a custom platform before proving a use case tends to delay the value it was meant to deliver. In-house platforms tend to make more sense only after a pilot has proven the use case and the business can justify the ongoing internal capacity to run it.
What is the difference between MLOps and LLMOps?
MLOps covers the practices for deploying and maintaining predictive machine learning models, while LLMOps applies similar discipline specifically to large language models, which introduce added considerations like prompt management and output evaluation. For most SMBs starting out, the pilot-first approach and monitoring basics described for MLOps apply directly, with LLM-specific tooling added only once a language-model use case is in scope.
How do I know if my business is ready to start an MLOps pilot?
Readiness shows up as a specific, measurable use case, access to relevant existing data, and at least one person who can own the pilot internally even with fractional technical support. Running a structured readiness assessment against a staged adoption model helps locate where your business actually stands before committing to a pilot scope.



