

Published on
Enterprise Leaders: 3 Steps to Prioritize Generative AI Use Cases
The generative AI categories delivering the fastest business value right now are productivity automation, customer personalization, content and media generation, and early agentic workflows that chain multiple tasks together. The right first move is not a company-wide rollout. It is choosing one or two narrow pilots, defining success metrics before launch, and building governance into the process from day one, not bolted on afterward.
TL;DR:
Break workflows into discrete tasks, then prioritize work with high automatability and error tolerance; defer decisions involving safety, money, or legal exposure.
Set function specific KPIs and a rollback trigger before launch; compare marketing results with a control group and support or engineering results against baselines.
Plan for integration, monitoring, and human review, which usually cost more than model fees; assign named owners for system, risk, and final approval.
Run most pilots for six to twelve weeks, with review intensity matched to risk; sensitive customer, financial, legal, and clinical outputs require human signoff.
BRDGITTurn AI Priorities Into Practical ActionBRDGIT helps teams identify AI opportunities, build clear roadmaps, and implement systems that address real business needs.Explore BRDGIT’s AI support
Table of Contents
Top generative AI use cases by business function
High-impact generative AI use cases by industry
How to identify and prioritize generative AI use cases
Implementation checklist: operationalizing NIST AI RMF for generative AI pilots
Measuring ROI and running pilots: KPIs, timelines, and cost considerations
Team BRDGIT perspective: practical next steps and where fractional support helps
FAQ
Sources
We help you turn these use cases into a working pilot, not just a plan
Top generative AI use cases by business function
Most organizations do not need a grand AI strategy document before they start. They need to know which tasks, inside which departments, are ready for a language model today and which ones still require a human holding the pen. The function-by-function view makes that distinction obvious, and it is where many organizations reported using generative AI in at least one business function in 2024 (https://hai.stanford.edu/ai-index/2025-ai-index-report), up sharply from the year before.
Marketing has become the proving ground for most teams, largely because the error tolerance is forgiving. A draft ad headline that misses the mark gets revised before it ever reaches a customer. Generative models now produce first-pass ad creative, subject lines, and personalized email variants at a volume no copywriting team could match alone. The KPI that matters here is not “did we generate more content,” it is click-through rate and conversion lift against a human-written control. Teams that skip the control group end up guessing whether the AI variant actually outperformed the old one.
Customer service carries more risk, because a wrong answer reaches the customer directly. The highest-value pattern is retrieval-augmented generation, where the model answers from a company’s own documentation instead of its general training data, cutting down on invented answers. Alongside that, automated ticket summarization and draft response generation for contact-center agents let humans review and send rather than type from scratch. Human-in-the-loop review stays mandatory for anything touching billing, refunds, or account access.
Engineering and IT teams tend to adopt generative AI fastest, for an obvious reason: code is testable. Code generation and autocompletion, automated unit test creation, and natural-language interfaces that let non-technical staff query legacy systems without writing SQL all fall into this bucket. Error tolerance is moderate: a flawed code suggestion gets caught in review or by the test suite, but a natural-language wrapper around a production database needs guardrails against destructive queries.
HR functions benefit from generative AI in lower-stakes, higher-volume tasks: summarizing candidate resumes against a job description, drafting onboarding materials, and building internal knowledge assistants that answer policy questions without a ticket to HR. The risk here is quieter but real. A screening summary that reflects biased training data can filter out qualified candidates before a human ever sees the resume, which is why screening outputs need human review, not automated rejection.
Finance and operations use generative AI for drafting narrative sections of reports, assisting with reconciliation explanations, and supporting forecasting with scenario narratives generated from underlying models. These tasks demand tighter human oversight than marketing copy, since a misstated number in a board report carries real consequences.
Legal and compliance teams are using generative AI for contract summarization and compliance triage, flagging clauses or filings that need attorney review rather than replacing that review. This is squarely a human-in-the-loop category: the model’s job is to surface what needs attention, not to make the final call.
Marketing: automated creative and messaging, measured by click-through rate and conversion lift.
Customer service: RAG-powered assistants and ticket summarization, with mandatory human review for sensitive requests.
Engineering and IT: code generation, test authoring, and natural-language database queries, checked by existing test suites.
HR: resume summarization and onboarding content, always paired with human screening decisions.
Finance: reconciliation drafting and forecast narratives, reviewed before any external reporting.
Legal: contract and compliance triage, routed to attorneys for final judgment.
Pro Tip: Match the pilot’s risk level to its review intensity: low-stakes drafting tasks need a quick human glance, while anything touching money, legal exposure, or customer access needs a defined sign-off step before it ships.
High-impact generative AI use cases by industry
Function-based use cases translate differently depending on what an industry actually produces and who it answers to. A few patterns show up repeatedly across sectors, each shaped by that industry’s own tolerance for error and its regulatory exposure.
Manufacturing teams are pairing generative models with sensor data to produce plain-language summaries of predictive maintenance alerts, turning a stream of vibration and temperature readings into a sentence a floor supervisor can act on without an engineering degree. Multimodal models that combine image and text are also showing up in visual inspection, flagging defects and explaining what was found, while digital-twin platforms use generative scenario creation to simulate production changes before they happen on the line. Google Cloud’s compilation of real-world generative AI deployments documents several of these multimodal factory applications in active use. For supply chain visibility specifically, generative AI tools are improving forecasting and inventory management by turning scattered logistics data into usable, timely narratives.
Healthcare sits at the higher-risk end of the spectrum, and for good reason. Clinical-document summarization, condensing a patient’s chart into the handful of facts a clinician needs before a visit, has clear value and relatively contained risk when a human still reads the summary. Synthetic data generation for training diagnostic models is gaining traction as a way to expand training sets without exposing real patient records. Patient-facing triage assistants are the category that demands the most caution: they can help route symptoms to the right level of care, but they need rigorous validation and a clear, visible handoff to a human clinician before any clinical judgment is implied.
Retail and e-commerce have moved quickly on catalog enrichment, using generative models to write product descriptions at scale from structured attributes, and on automated product imagery and short-form video, cutting the time between a new SKU landing in inventory and that SKU having a sellable listing. Personalized recommendation narratives, explaining to a shopper why a product was suggested, add a layer of trust that a bare recommendation engine does not.
Finance firms are deploying conversational assistants for routine banking workflows, like balance inquiries and transaction explanations, alongside document ingestion systems that pull structured data out of unstructured KYC paperwork and flag compliance exceptions for a human analyst. The common thread is triage, not autonomous decision-making, on anything regulatory.
Media and advertising have adopted generative AI for producing creative variants at a volume that would be uneconomical by hand and for localizing campaigns across languages and markets without restarting the creative process from scratch each time.
Logistics operations are using generative AI to turn route-optimization output into incident reports and operational narratives a dispatcher can read in seconds, while multimodal monitoring systems track inventory and flag anomalies across warehouse camera feeds.
Manufacturing: maintenance summaries, visual inspection, and digital-twin scenario generation.
Healthcare: document summarization and synthetic training data, with mandatory human oversight for anything patient-facing.
Retail: catalog enrichment, generated imagery, and recommendation narratives.
Finance: conversational banking assistants and KYC document triage.
Media: creative variant generation and multilingual localization at scale.
Logistics: incident narratives and multimodal inventory monitoring.
How to identify and prioritize generative AI use cases
Picking the wrong first pilot is the single most common way organizations sour on generative AI before it has a chance to prove itself. MIT Sloan’s research on finding the right use cases lays out a three-step method that holds up well in practice, and it starts smaller than most teams expect.
Decompose the job into discrete tasks. A role like “customer support representative” is not one task, it is dozens: reading a ticket, searching documentation, drafting a reply, escalating edge cases. Breaking workflows into tasks surfaces which pieces tolerate automation and which ones need a human’s judgment, often revealing low-hanging opportunities that a whole-job view would miss entirely.
Apply the generative-AI cost equation. License and compute fees are the visible cost, but integration work, ongoing monitoring, and the staff time needed to catch and fix errors usually cost more over a pilot’s lifetime than the model fees themselves, a pattern MIT Sloan’s practitioner research flags as the factor that most often determines whether a pilot survives past its first quarter.
Select narrow pilots with measurable KPIs. A task with high automatability and high error tolerance, like drafting a first-pass email, beats a task with high automatability but low error tolerance, like approving a loan, even though both look appealing on a feasibility chart.
A simple prioritization matrix helps here: plot each candidate task on automatability against error tolerance, and start with whatever lands in the upper right. Tasks requiring deep reasoning or carrying real safety consequences belong in a later phase, after the organization has built up review habits and monitoring infrastructure on something smaller.
Pro Tip: Write down the KPI and the rollback trigger for a pilot before you write a single prompt. If you cannot state in one sentence how you will know the pilot failed, you are not ready to launch it.
Implementation checklist: operationalizing NIST AI RMF for generative AI pilots
Governance frameworks tend to read as abstract until a team tries to launch an actual pilot, at which point the gap between “principle” and “action” becomes obvious fast. The NIST AI Risk Management Framework’s Generative AI Profile exists to close that gap, and it recommends integrating trustworthiness considerations across the entire AI lifecycle rather than treating risk review as a final checkbox before launch.
Translated into pilot-level action, that means:
Document your data. Record what training or retrieval data the model draws on, where it came from, and who has reviewed it for sensitive content.
Run staged TEVV. NIST’s framework calls for testing, evaluation, validation, and verification at each stage: unit tests for prompts and output parsing, adversarial red-teaming to surface harmful or embarrassing outputs, and production monitoring with alert thresholds tied to a defined rollback plan.
Set human review thresholds. Decide in advance which outputs ship automatically and which ones require sign-off, and make that threshold visible to the team running the pilot, not just to compliance.
Control access and handle PII deliberately. Apply least-privilege access to the model and its data sources, and use synthetic data wherever real personal information is not strictly necessary for the task.
Assign named roles. A product owner who owns the business outcome, an ML engineer who owns the system, a compliance lead who owns risk sign-off, and a human reviewer who owns the final check, are each a distinct person, not a shared assumption that “someone” will catch problems.
NIST’s own risk mapping guidance makes a point worth repeating here: governance actions should scale with the risk of the specific use case, not apply uniformly across every pilot. A marketing copy generator and a patient-triage assistant do not need the same level of oversight, and treating them identically either over-burdens the low-risk pilot or under-protects the high-risk one.
Rollback criteria deserve their own line item. A pilot without a clearly defined “we turn this off if X happens” condition tends to drift into production by default, simply because nobody made the decision to stop it.
Measuring ROI and running pilots: KPIs, timelines, and cost considerations
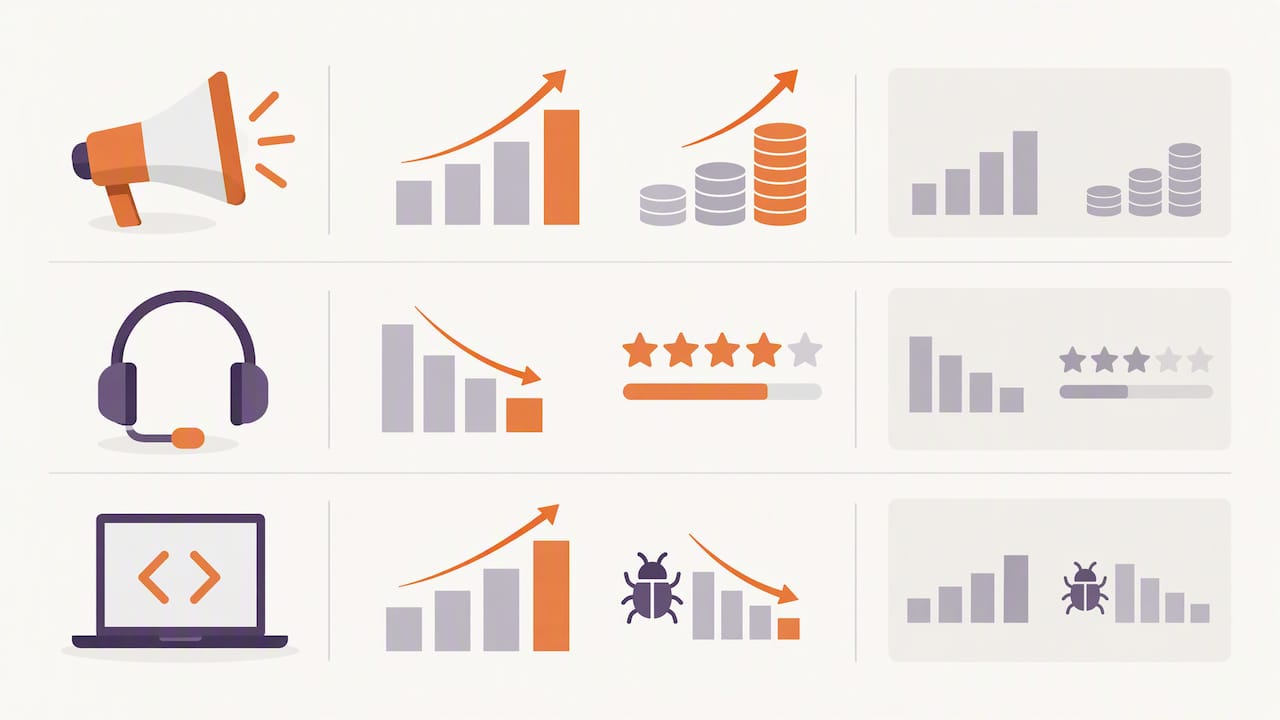
A pilot without a predefined success metric is just a demo that happens to run longer. The KPI has to match the function: marketing pilots live or die on engagement and revenue lift against a control group, support pilots on handle time and customer satisfaction score, and engineering pilots on throughput and defect rate compared with the pre-AI baseline.
Most well-scoped pilots run six to twelve weeks, long enough to gather a meaningful sample of real interactions without letting an underperforming pilot linger past the point where its lessons are still cheap to act on. Cost planning needs to account for more than the obvious line item: API or model fees are often the smallest piece, while integration work, ongoing monitoring, and human review staffing tend to dominate the real budget, a pattern consistent with MIT Sloan’s cost equation guidance.
Scaling a pilot that works requires real investment, not just a bigger budget line. Platformizing the workflow, building the data plumbing that feeds the model reliably, and extending the governance structure built for one pilot to cover a portfolio of them are the three places most scale-up efforts stall.
Marketing KPIs: engagement rate and revenue lift against a control group.
Support KPIs: average handle time and customer satisfaction score.
Engineering KPIs: throughput gains and defect rate versus baseline.
Typical pilot length: 6 to 12 weeks, with a predefined rollback condition.
Pilot factor | What to track |
|---|---|
Timeline | 6 to 12 weeks from launch to evaluation |
Primary cost driver | Integration and human review staffing, not model fees |
Success signal | KPI improvement against a measured baseline |
Scale-up requirement | Data plumbing and governance built for a portfolio, not one task |
Team BRDGIT perspective: practical next steps and where fractional support helps
Our honest read, after watching teams rush this: the pilots that work are almost boring in their narrowness. Run a short AI readiness check on your own workflows first. Pick one task, not a department. Write the KPI and the governance rule before anyone opens a prompt window.
The failure pattern we see most often is scope creep disguised as ambition: a pilot meant to summarize tickets grows into “automate the whole support queue” before week two. The fix is discipline, not more technology. Monitoring and remediation costs get ignored until they are the whole budget, and nobody owns the human review step until something slips through uncaught.
— Team BRDGIT
FAQ
What are the 7 general use cases for prompts in generative AI?
There is no single official list of seven, but commonly cited prompt categories include summarization, content drafting, code generation, question answering, classification, translation or localization, and brainstorming or ideation. Most business applications combine several of these within one workflow, such as a support assistant that both answers questions and summarizes tickets.
What are the top 10 use cases for AI?
Frequently cited top use cases span productivity automation, customer service assistants, marketing content generation, code generation and testing, personalized recommendations, document summarization, forecasting support, fraud and compliance triage, synthetic data generation, and agentic multi-step workflows. The specific ranking varies by industry and by how an organization defines “use case.”
How long should a generative AI pilot run before deciding whether to scale it?
Most well-scoped pilots run six to twelve weeks, enough time to gather a meaningful sample of real outcomes against a defined KPI. A pilot that lacks a predefined success metric or rollback condition tends to run indefinitely without ever producing a clear answer.
What is the biggest hidden cost in a generative AI pilot?
Model and API fees are usually the smallest line item. Integration work, ongoing monitoring, and the staff time needed for human review and error remediation typically cost more over a pilot’s life and often decide whether it is worth scaling.
How does BRDGIT help companies choose their first AI pilot?
Our AI Readiness Assessment is built to help a team identify which tasks are realistic first pilots based on automatability, error tolerance, and existing workflow data, rather than starting from a generic industry template.
Sources
We help you turn these use cases into a working pilot, not just a plan
Reading about generative AI use cases is the easy part. Translating one of them into a pilot that fits your actual systems, your actual team, and your actual risk tolerance is where most companies stall, usually because they are trying to do it without anyone on staff who has built one of these before.
That is the gap our AI Readiness Assessment and AI Blueprint services are built to close: we start with a practical audit of your workflows, identify which tasks are genuinely ready for automation, and build a modular rollout plan that integrates with what you already run instead of asking you to rip it out. For teams that need hands-on build work or ongoing support without hiring a full-time AI engineer, our Fractional Engineer Services put experienced AI talent on your project for exactly as long as the work requires.
If you have a task in mind and want a second opinion on whether it is a good first pilot, get in touch through Brdgit and we will walk through it with you.



